Drogon#
Note
In the current implementation of the pycopm tool, the handling of properties that requires definitions of i,j,k indices (e.g., FAULTS, WELLSPECS) are assumed to be defined in the main .DATA deck. Then, in order to use pycopm for simulation models where these properties are define via include files, replace those includes in the .DATA deck with the actual content of the include files. Here are some relevant keywords per deck section that need to be in the main input deck and not via include files:
SECTION GRID: MAPAXES, FAULTS, MULTREGT (other keywords like MULTZ, NTG, or definitions/operations for perms and poro can be in included files since permx, permy, permz, poro, porv, multx, multy, multz are read from the .INIT file)
SECTION PROPS: EQUALS, COPY, ADD, and MULTIPLY since this involve i,j,k indices and are applied to properties such as saturation functions parameters that are still given in the same input format in the generated deck. In addition, SWATINIT if used in the deck, is read from the .INIT file and output for the modified deck in a new file, then one might need to give the right include path to this special case.
SECTION SCHEDULE: All keywords in this section must be in the input deck and no via include viles.
Following the note above, then by downloading the DROGON model, adding the MAPAXES to the deck, replacing the lines in DROGON_HIST.DATA for the FAULTS (L127-128) and SCHEDULE (L242-243) with the actual content of those include files, then by executing:
pycopm -i DROGON_HIST.DATA -c 1,1,3 -p 1 -q 1 -l C1
pycopm -i DROGON_HIST_PYCOPM.DATA -c 1,3,1 -p 1 -q 1 -j 2.5 -l C2 -m all
this would generate the following coarsened model:
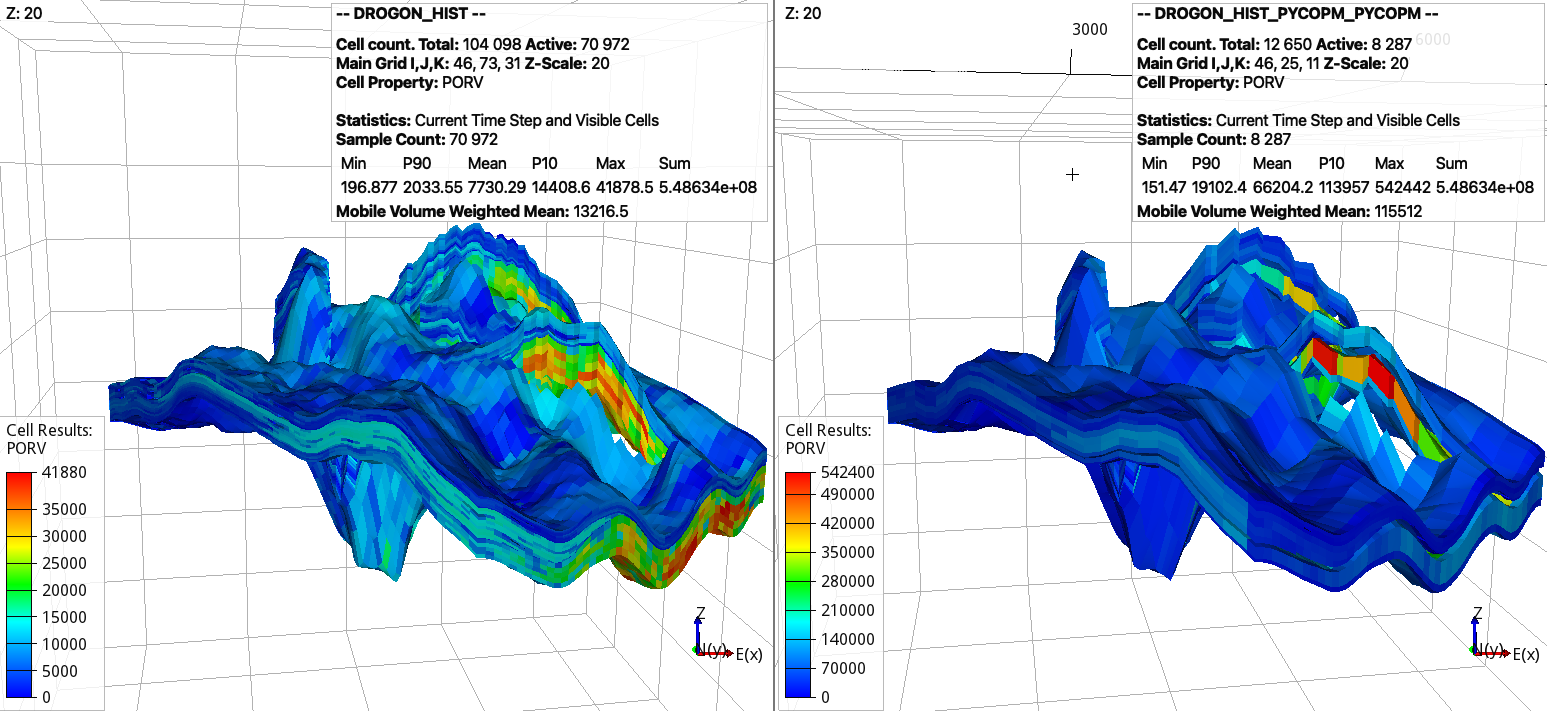
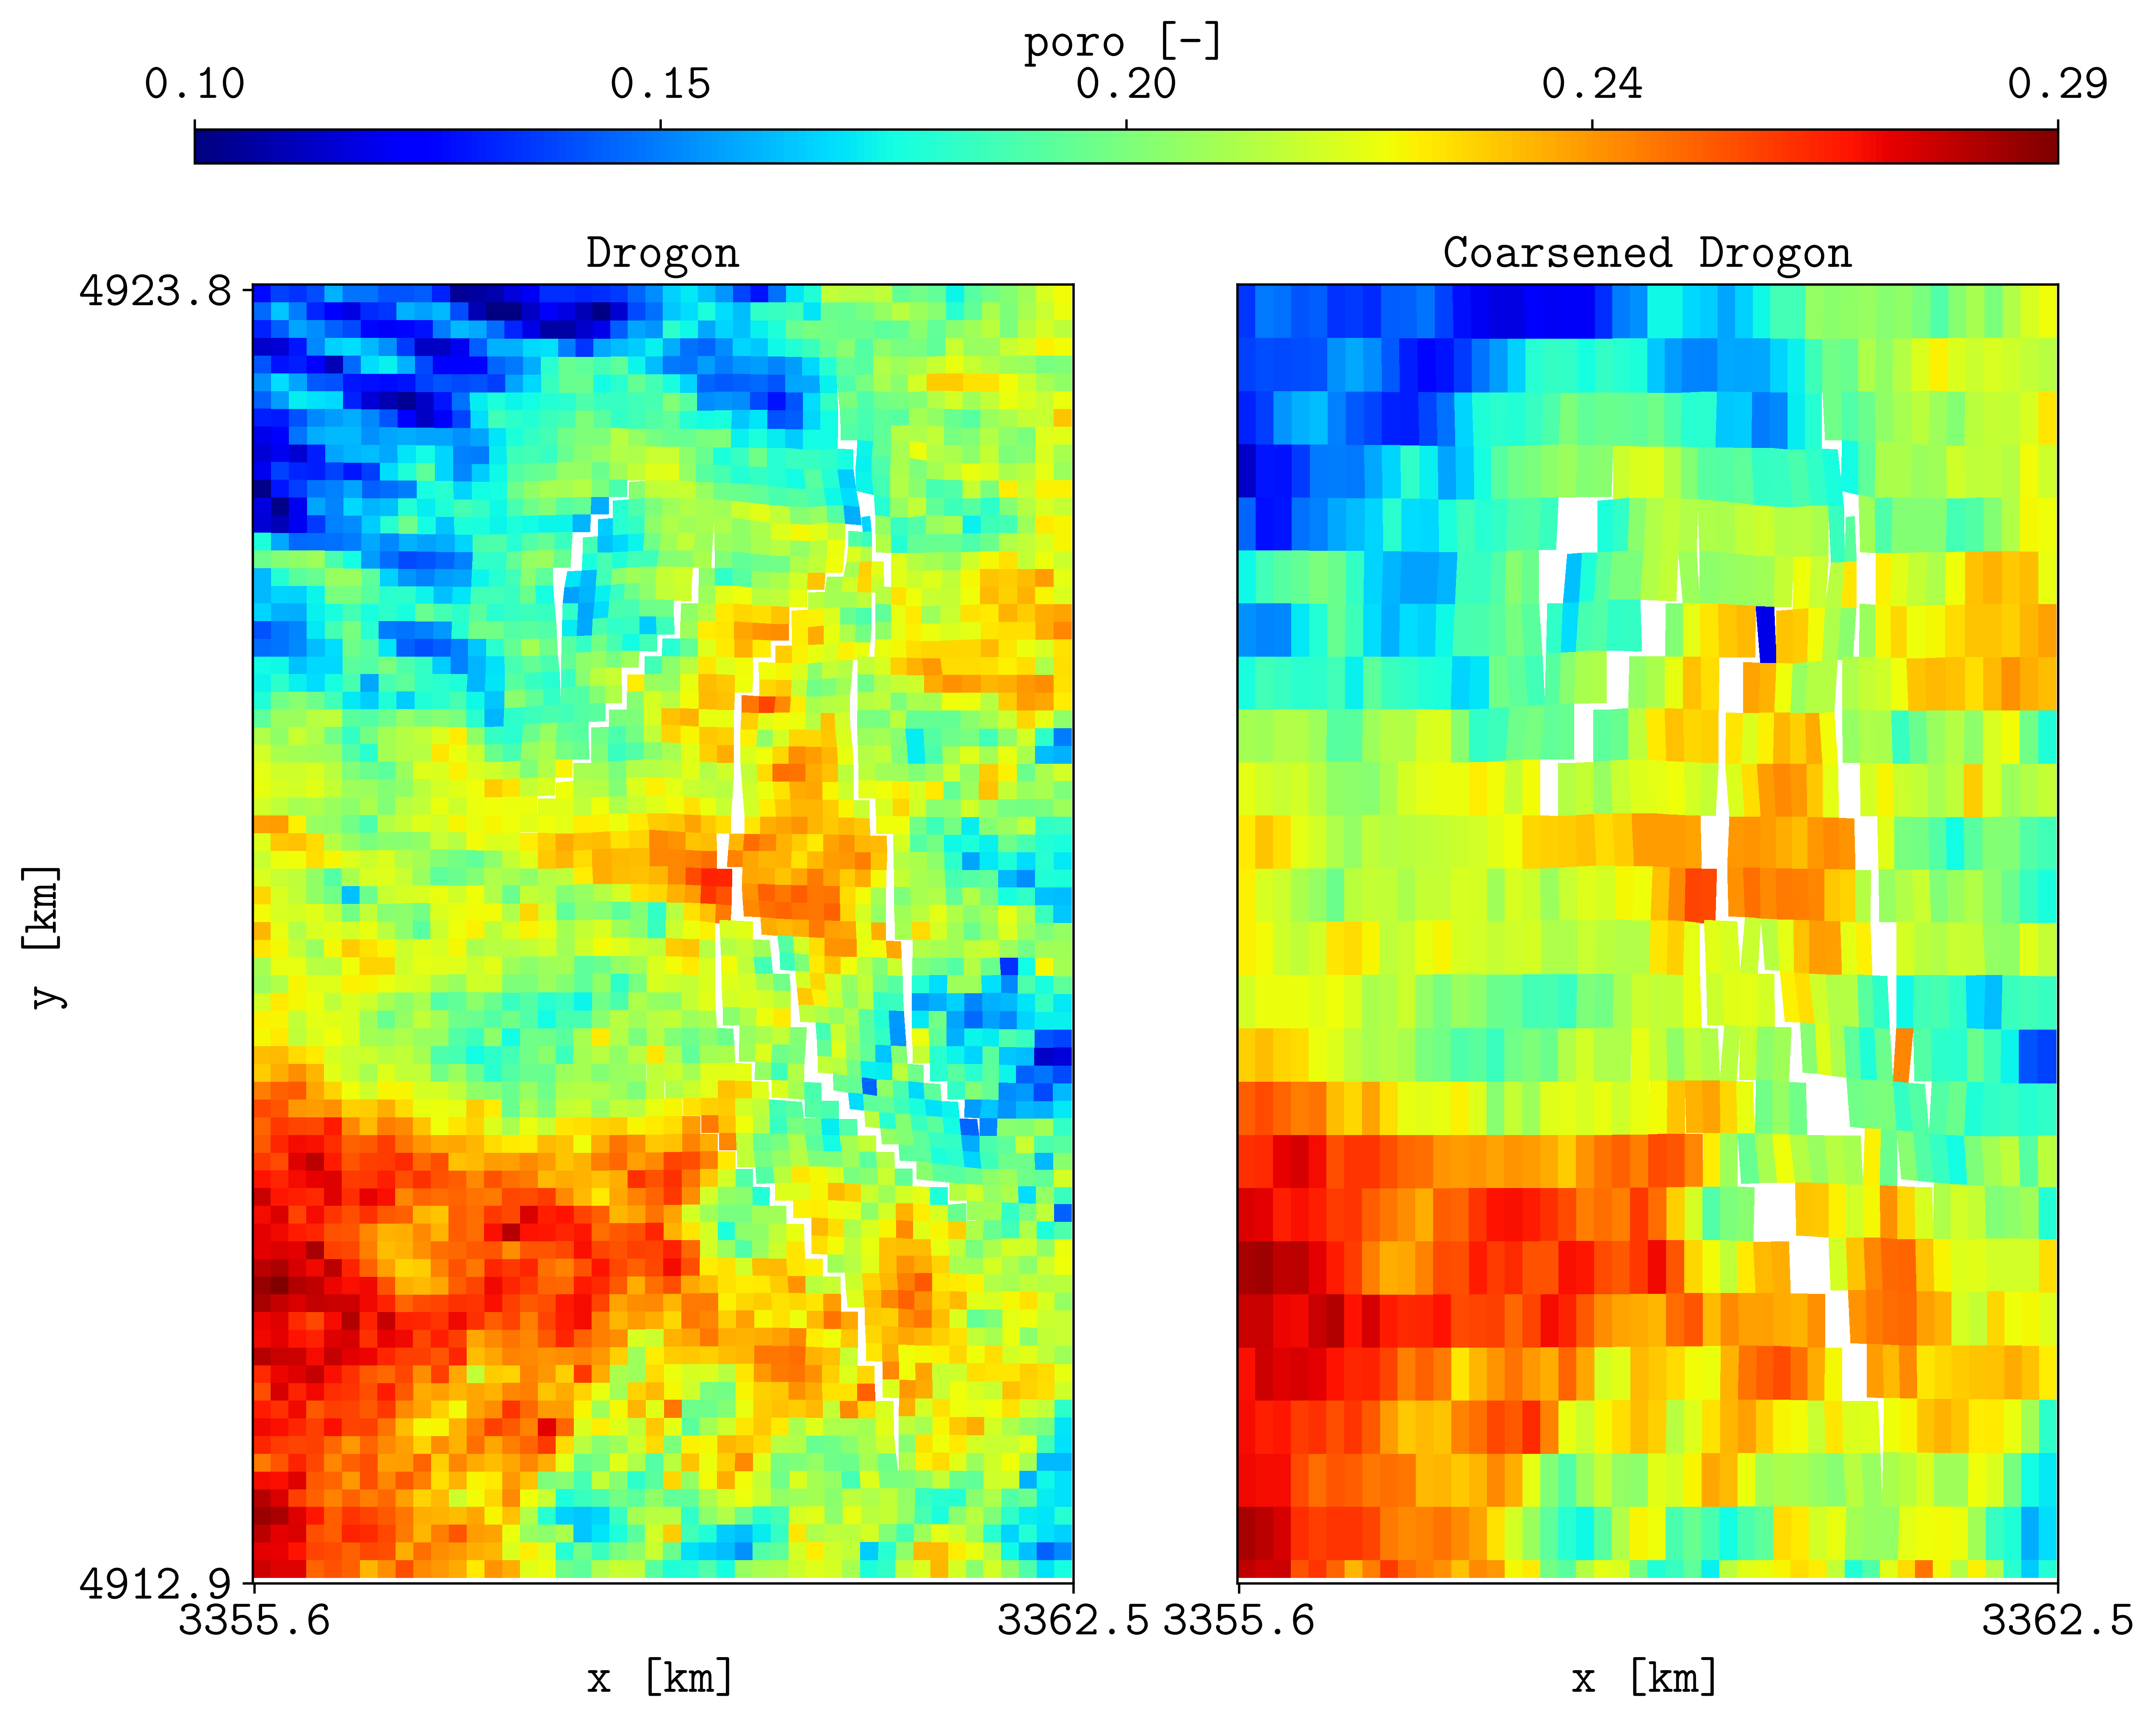
Note that the total pore volume is conserved for the coarsened model (right). The properties of the standard model (left) can be visualized using the DROGON_HIST_PREP_PYCOPM_DRYRUN generated files (top figures using ResInsight and bottom figures using plopm, see/run docs_via_deck_drogon.sh).#
Here, we first coarse in the z direction, which reduces the number of cells from 31 to 11, and after we coarse in the y direction. After trial and error, the jump (-j) is set to 2.5 to avoid generated connections across the faults. For geological models with a lot of inactive cells and faults, this divide and conquer apporach is recommended, i.e., coarsening first in the z direction and after coarsening in the x and y directions. Also, we add labels (-l) C1 and C2 to differentiate between the coarse include files. In addition, we use the flags -p 1 -q 1 to add the remove pore volume to the closest coarser cells and to redistribute the pore volume in the locations with gas and oil, this results in the coarsened model having the same total pore volume, field gas in place, and practically same oil and water in place as the input model.
Note
Add to the generated deck the removed include files in the grid section related to the region operations (e.g., ../include/grid/drogon.multregt for this case).
Now, we also show a two times coarsened model in all directions (referring to the previous comment about divide and conquer, for the Drogon model it seems still ok to do a two times coarsening in one go):
pycopm -i DROGON_HIST.DATA -c 2,2,2 -p 1 -q 1 -j 4 -w DROGON_2TIMES_COARSER -m all
Here, we use the -w flag to give a specific name to the generated coarsened deck, as well as using a higher value of -j to avoid generated connections across the faults.
Tip
To use a different approach from the default ones (see the theory) to coarse one of the properties (e.g., permeabilities), this can be achieve by the -s flag, e.g., -s pvmean to coarse the permeabilities using a pv-weighted mean. In addition, one could add a different label -l pvweightedperms to identify the generated .INC files with the permeabilities, and rename these files in order to be used in the coarserned model with the rest of the properties using the default aproaches or a combination of them (e.g., -s max -l maxpermz and keep the maximum values of permz).
If we run these three models using OPM Flow:
flow DROGON_HIST.DATA
flow DROGON_HIST_PYCOPM_PYCOPM
flow DROGON_2TIMES_COARSER
then we can compare the summary vectors. To this end, we use our good old friend plopm:
plopm -i 'DROGON_HIST DROGON_HIST_PYCOPM_PYCOPM DROGON_2TIMES_COARSER' -v 'FOIP,FOPR,TCPU' -tu y -fz 14 -sg 2,2 -rdl 1 -ll empty,empty,empty,center -fs 10,5 -xf '.1f' -xnt 6 -yl 'sm$^3$ sm$^3$/day seconds' -t 'Field oil in place Field oil production rate Simulation time' -llb 'DROGON DROGON 3XZ COARSER DROGON 2XYZ COARSER' -fn drogon_pycopm_comparison -yf '.2e,.0f,.0f'
Note that the coarsened models have the same initial field oil in place as the input model. It seems the coarsened properties (e.g., permeabilities) are good initial inputs to use in a history matching framework (e.g., to history match saturation function parameters), and the lower simulation time for the coarsened models allow for more ensemble members and more iterations (figures using plopm, see/run docs_via_deck_drogon.sh).#
We can also make a nice GIF by executing:
plopm -i 'DROGON_HIST DROGON_HIST_PYCOPM_PYCOPM DROGON_2TIMES_COARSER' -v sgas -sg 1,3 -fs 15,11 -cbn 5 -m gif -xnt 4 -ynt 4 -dpi 300 -t "DROGON DROGON 3XZ COARSER DROGON 2XYZ COARSER" -fz 16 -gi 2000 -gl 1 -cbf .2f -cbp 0.15,0.93,0.7,0.02 -s ,,1 -rot '-30' -xu km -yu km -xf .0f -yf .0f -c cet_rainbow_bgyrm_35_85_c69 -rdl 1 -tu tstep
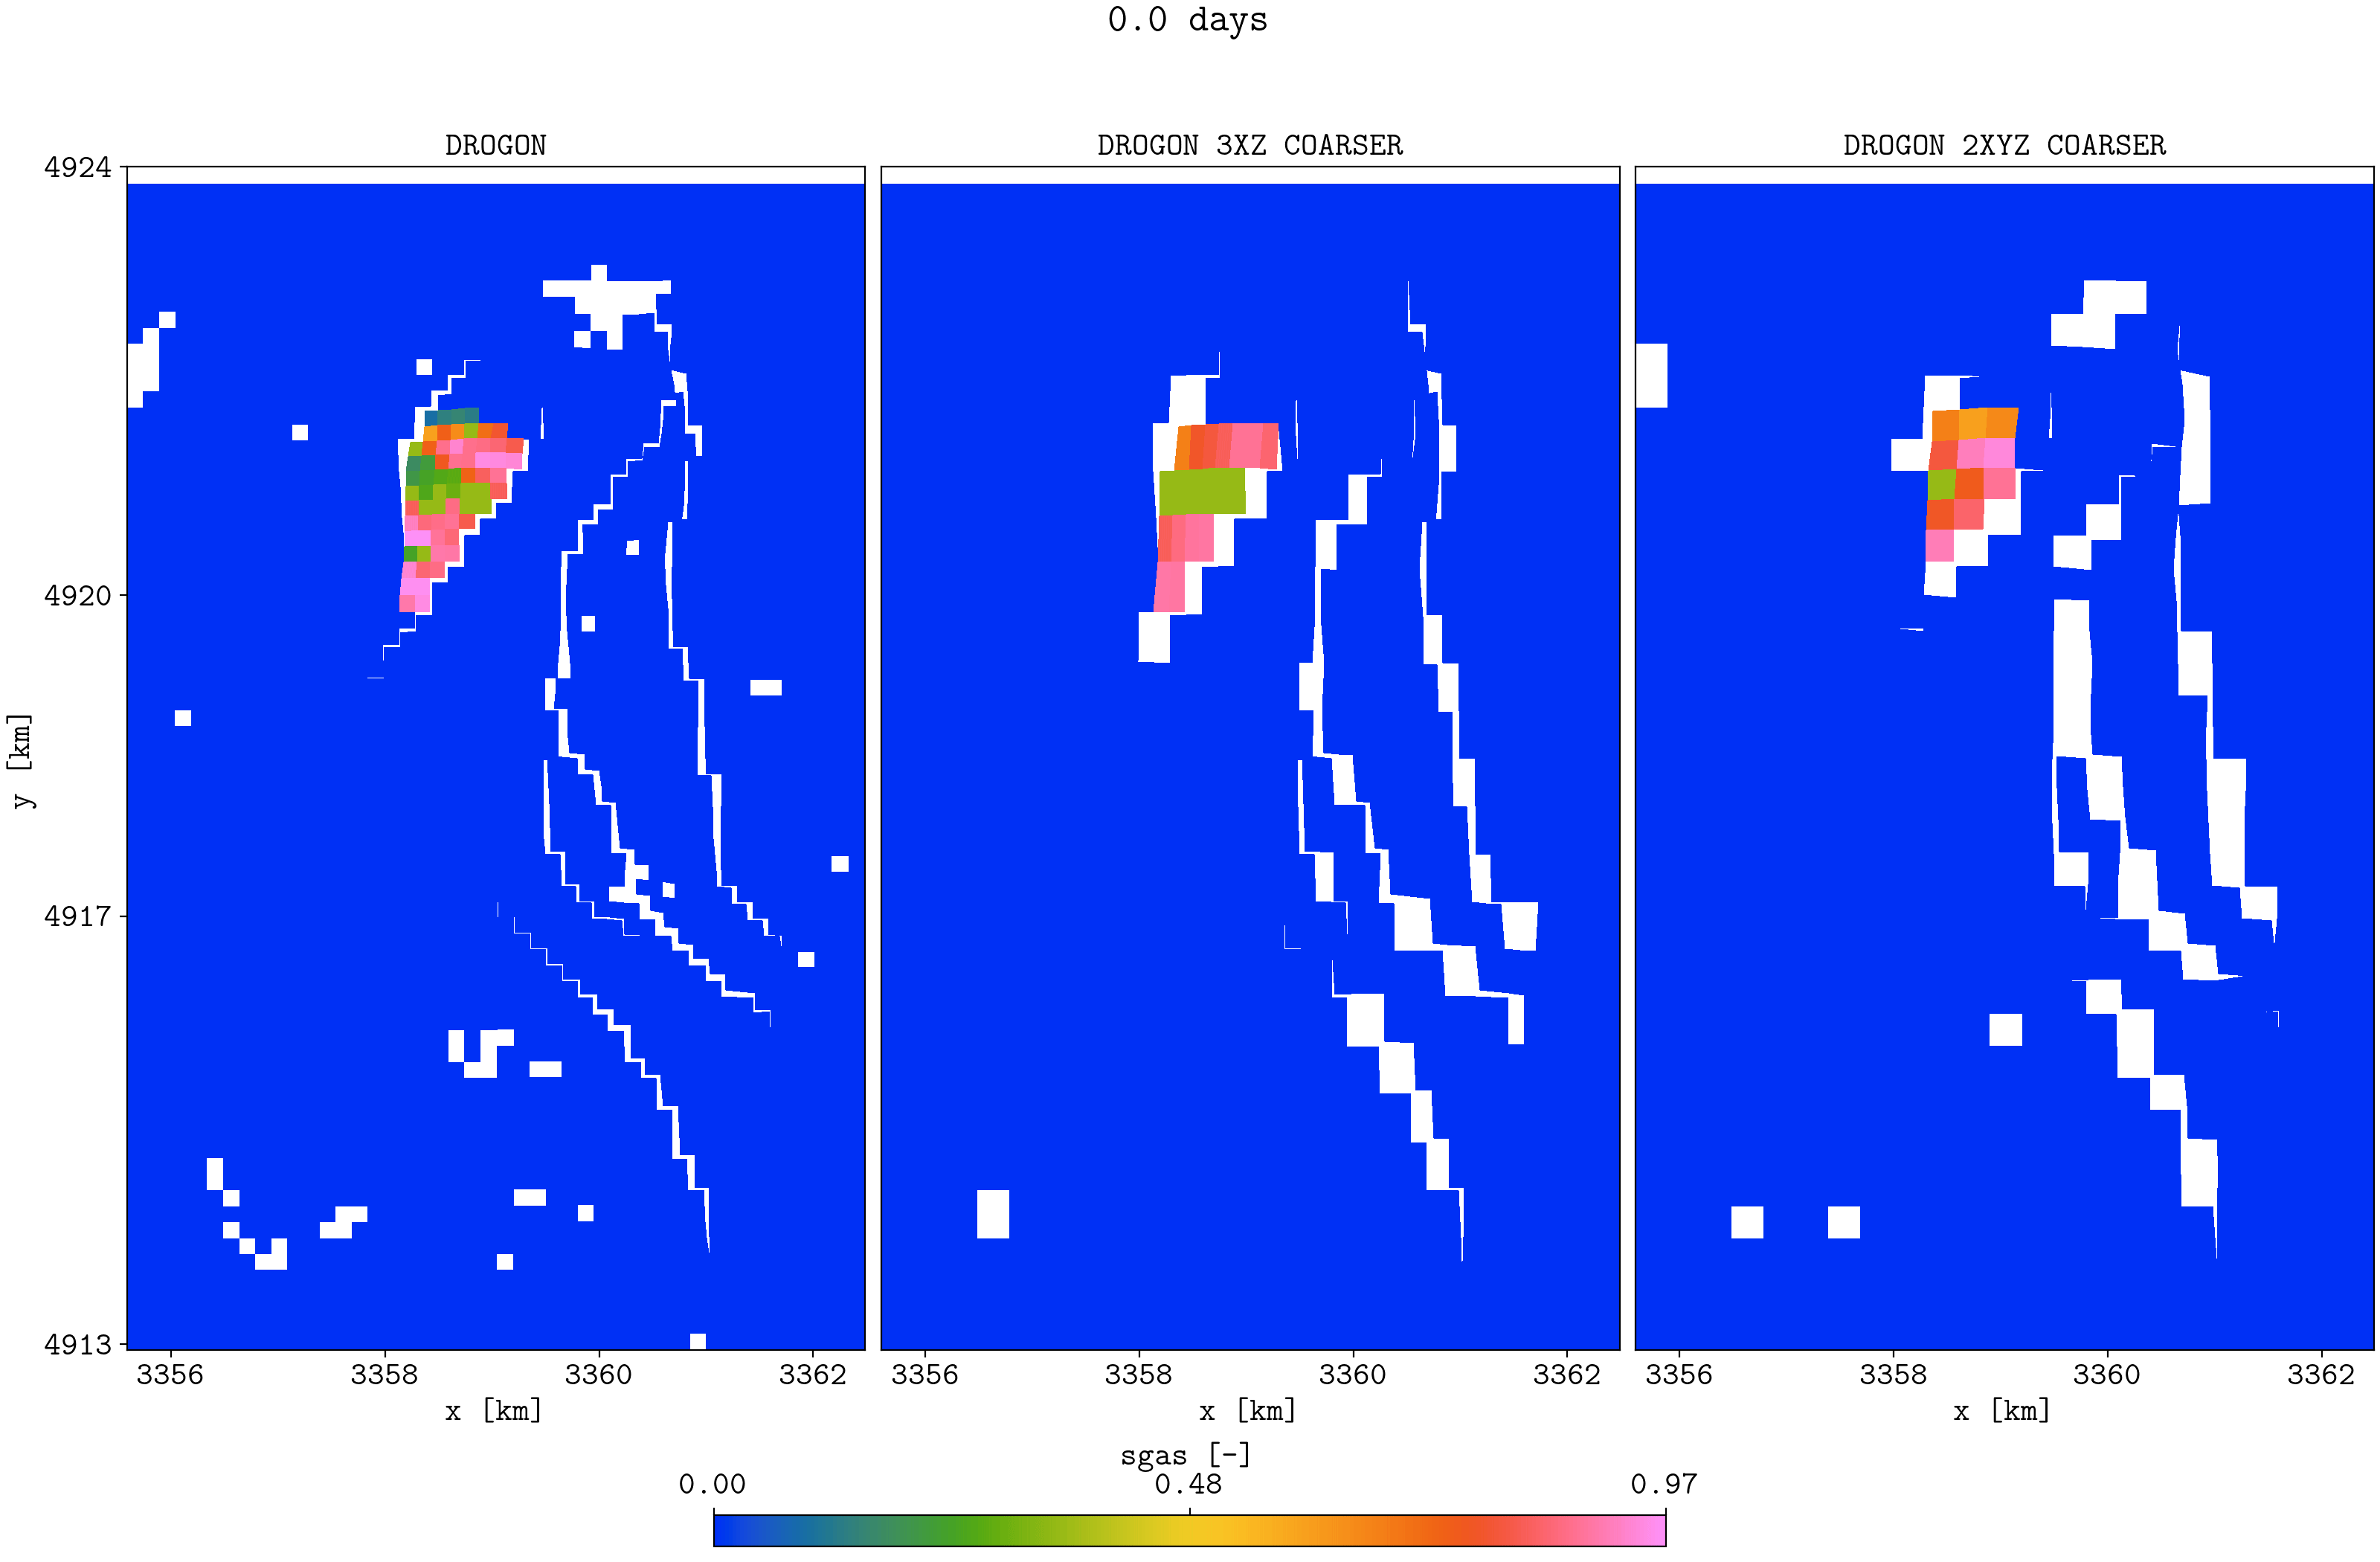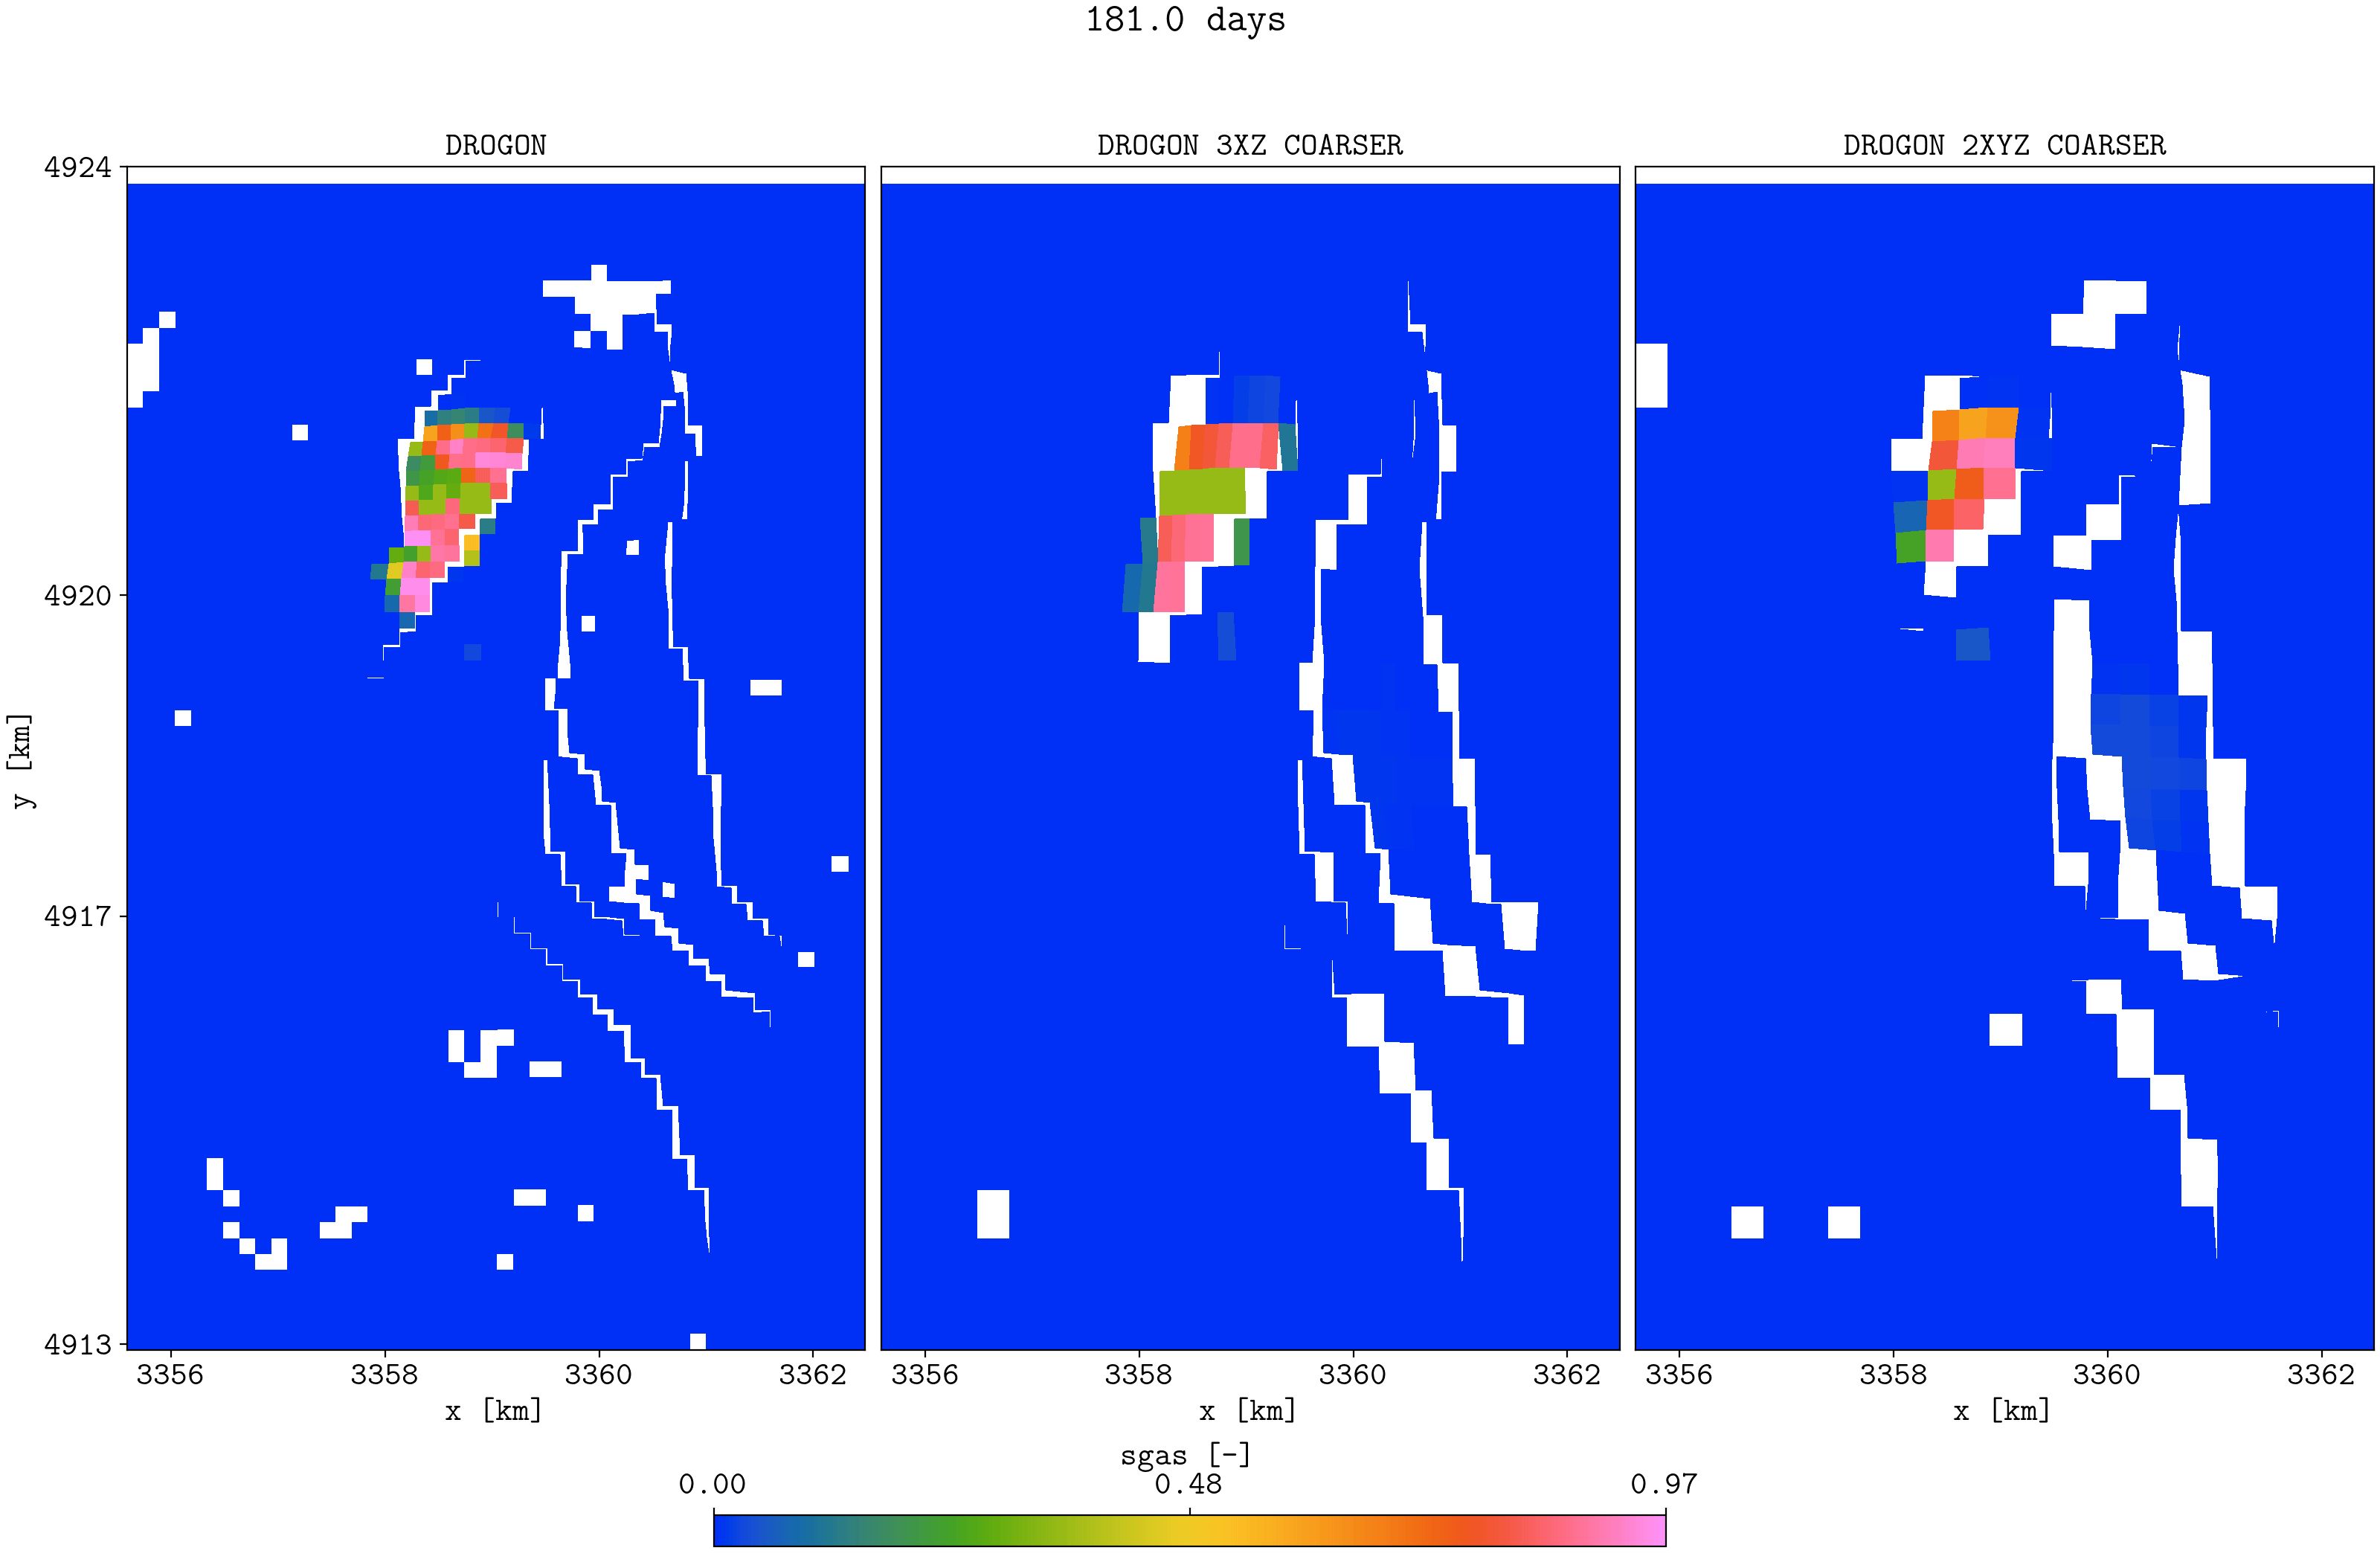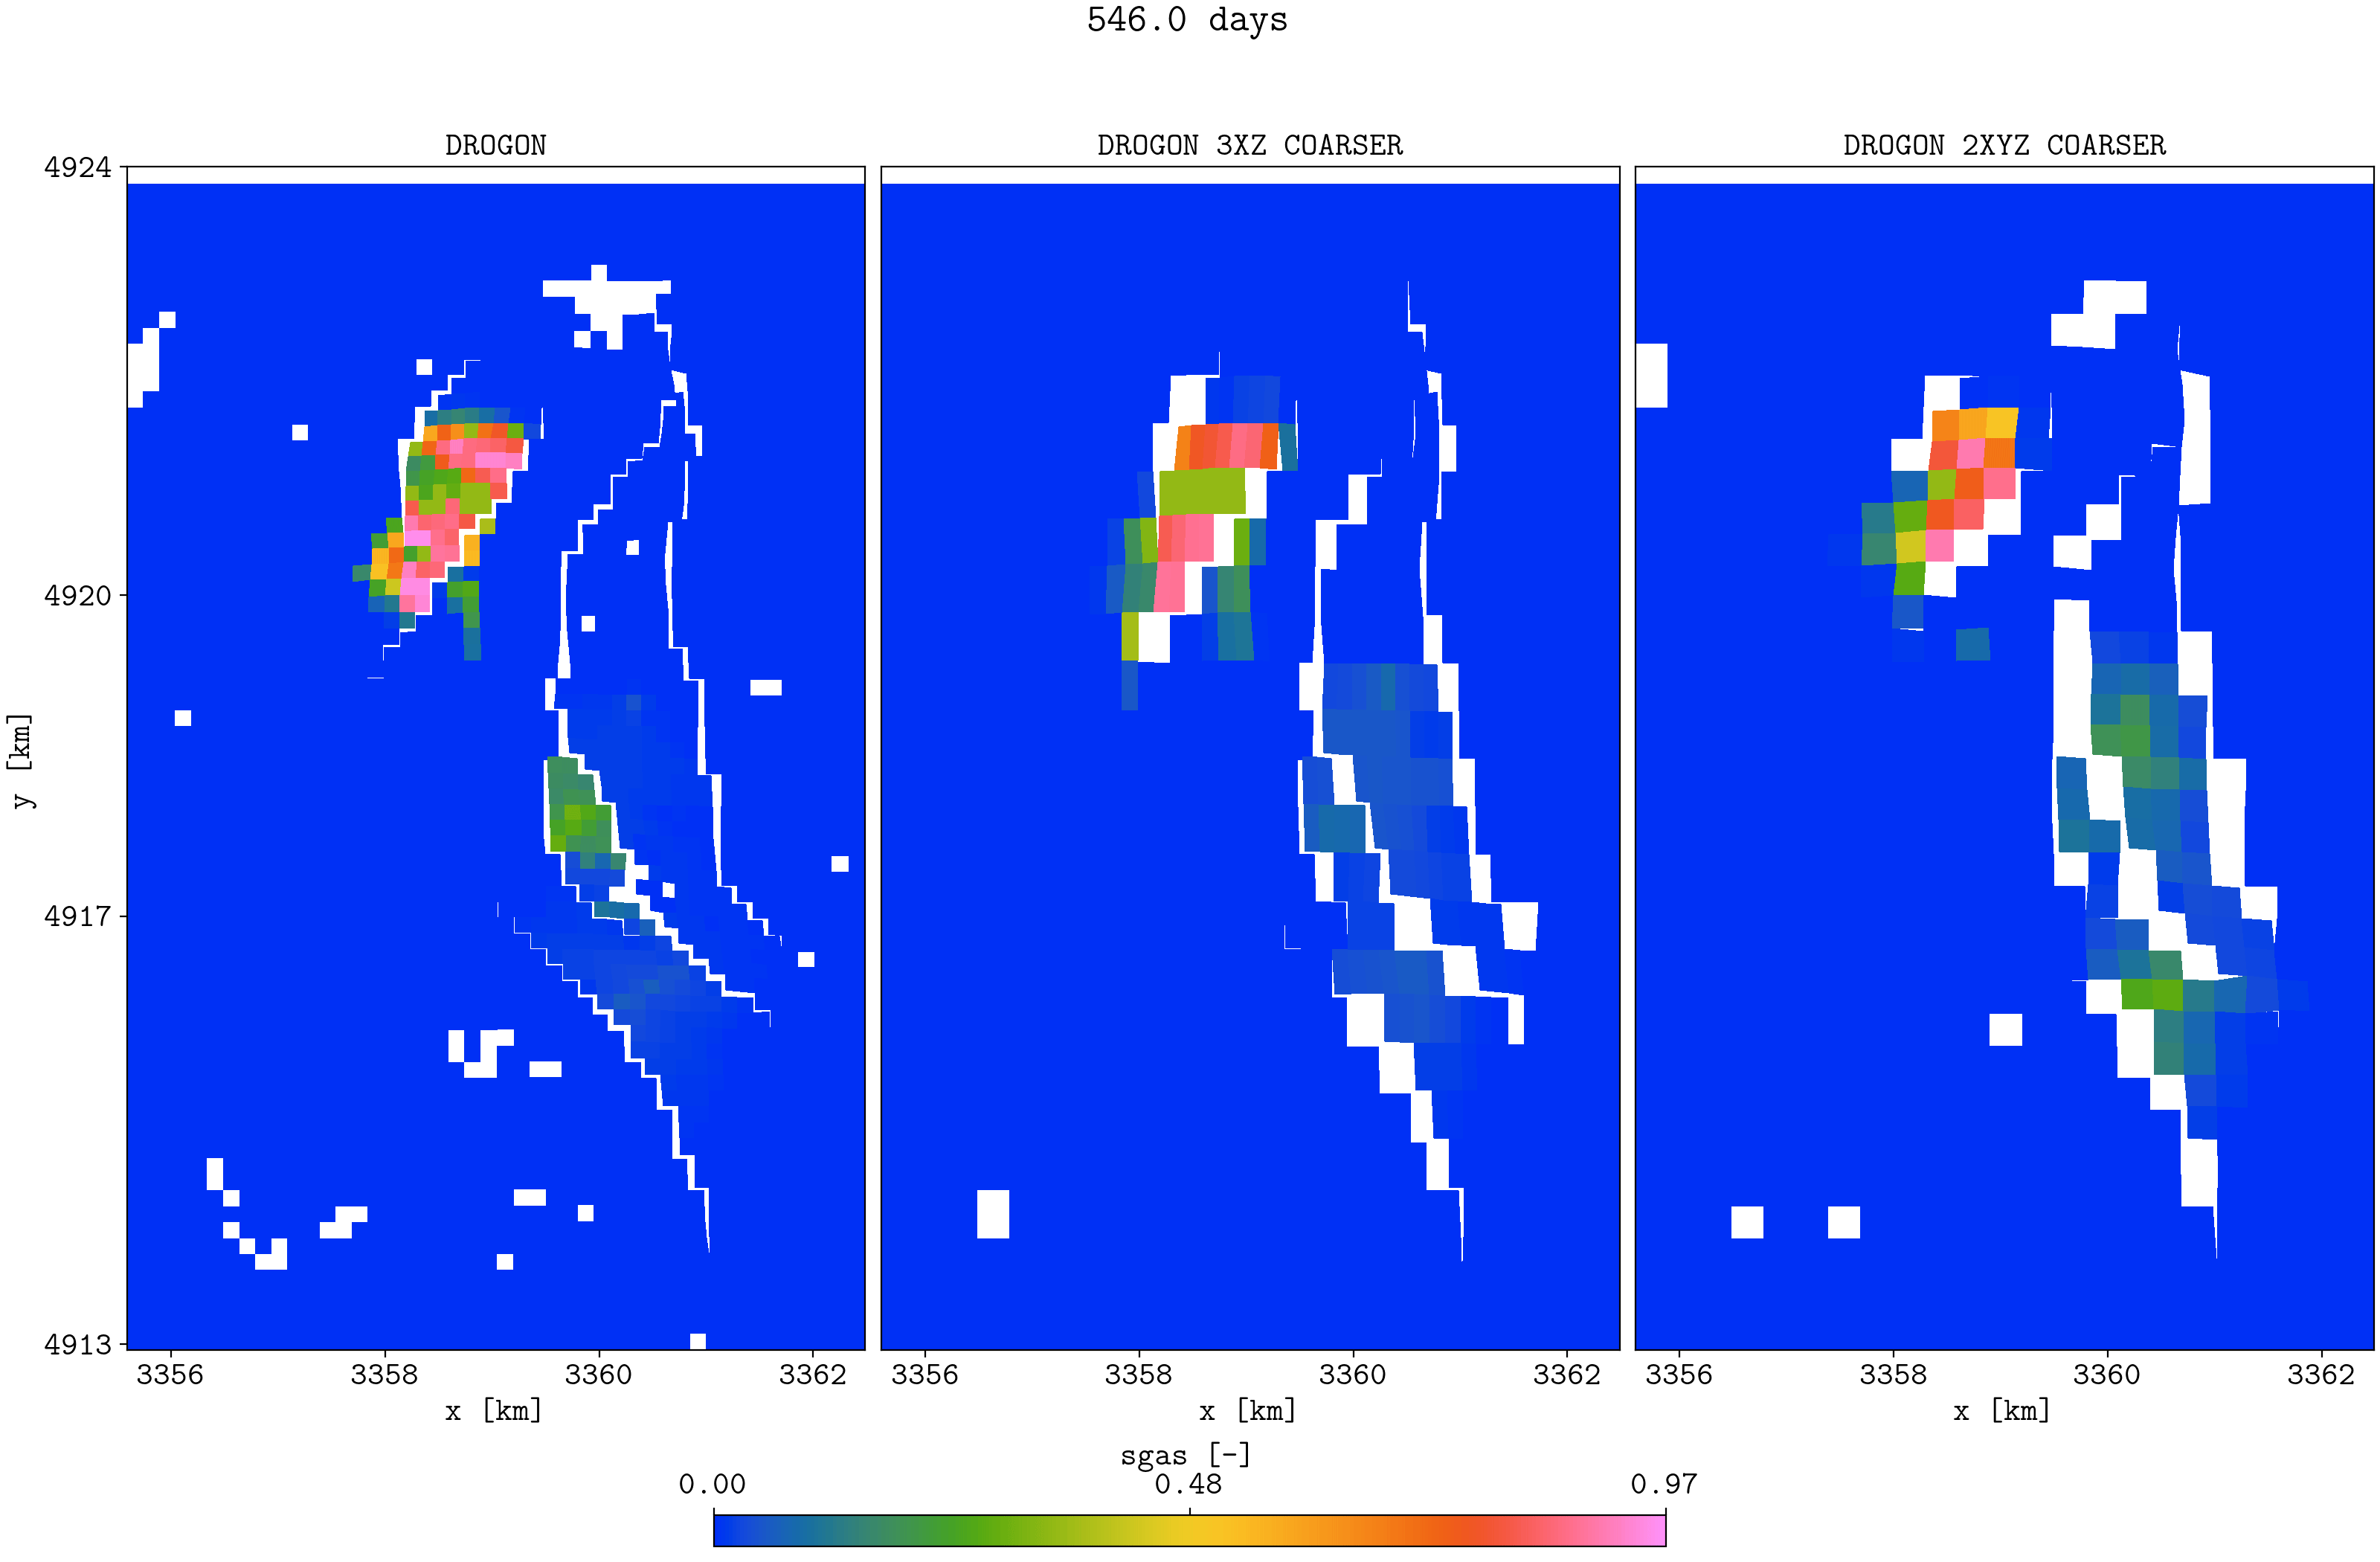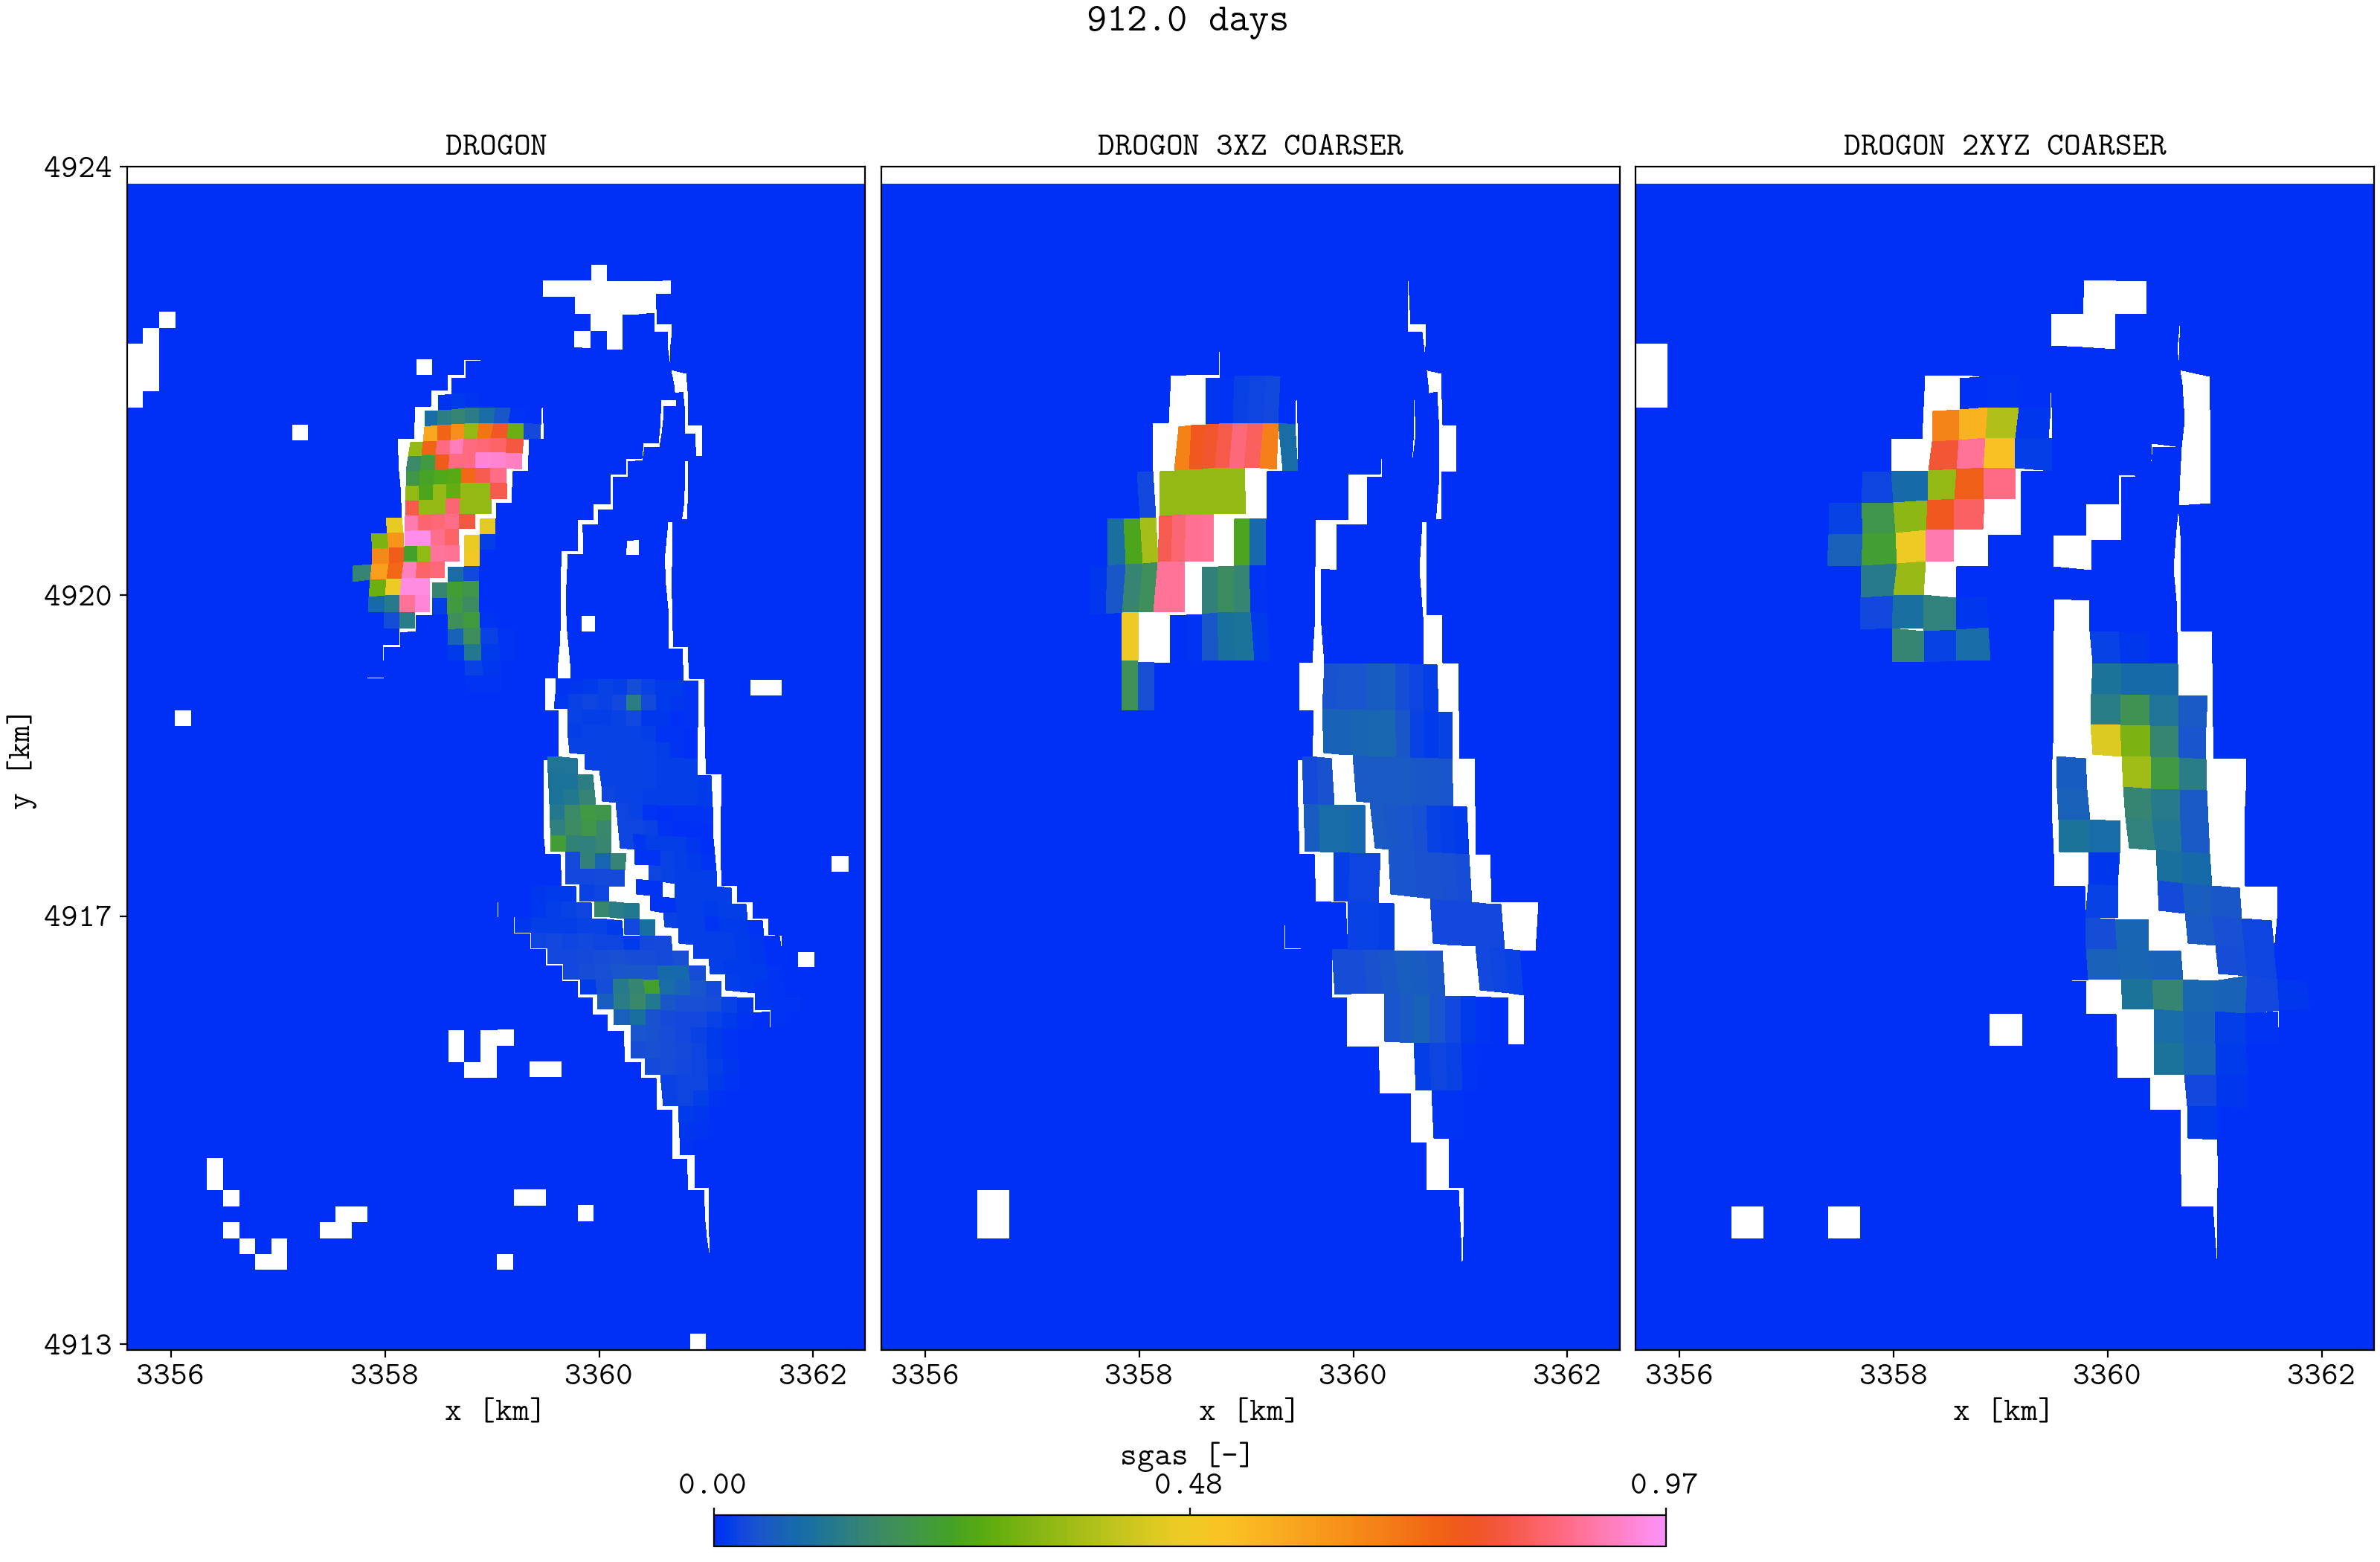
Top view of the Drogon and the two coarsened models (figures using plopm, see/run docs_via_deck_drogon.sh).#